The Full Transformer, Encoder + Decoder
Attention is the star. Everything else, residuals, normalization, feed-forward, cross-attention, is the scaffolding that lets you stack it deep.
The Problem
A single attention layer is a feature extractor, not a model. One matmul per layer is not enough capacity for language. You need depth, and depth breaks without the right plumbing.
The 2017 Vaswani paper packaged six design decisions that turned one attention layer into a stackable block. Every transformer since, encoder-only (BERT), decoder-only (GPT), encoder-decoder (T5), inherits the same skeleton. In 2026 the blocks have been refined (RMSNorm, SwiGLU, pre-norm, RoPE) but the skeleton is identical.
This lesson is the skeleton. Next lessons specialize it, 06 for encoders, 07 for decoders, 08 for encoder-decoder.
The Concept
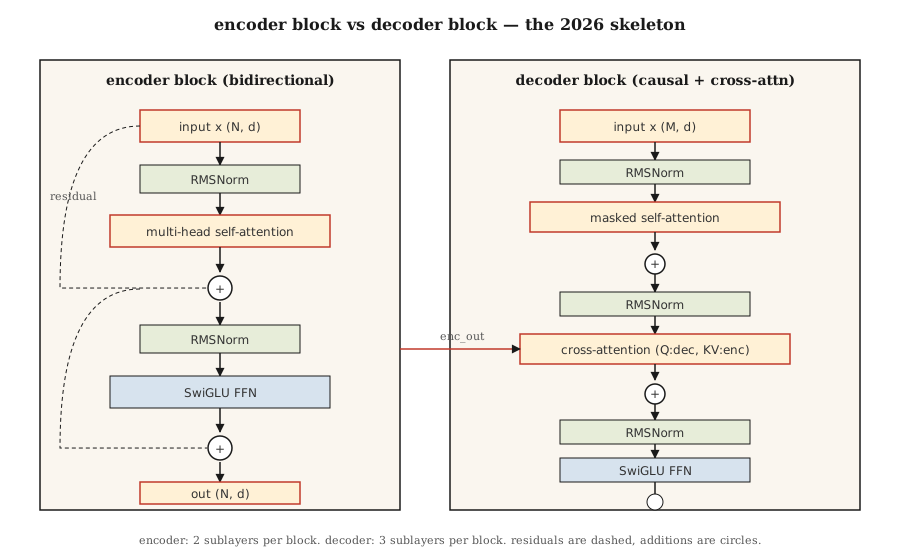
The six pieces
- Embedding + positional signal. Tokens → vectors. Position injected via RoPE (modern) or sinusoidal (classic).
- Self-attention. Every position attends to every other. Masked in decoders.
- Feed-forward network (FFN). Position-wise two-layer MLP:
W_2 · activation(W_1 · x). Expansion ratio 4× by default. - Residual connection.
x + sublayer(x). Without this, gradients vanish past ~6 layers. - Layer normalization.
LayerNormorRMSNorm(modern). Stabilizes the residual stream. - Cross-attention (decoder only). Queries come from the decoder, keys and values from the encoder output.
Watch a vector flow through one block: attention mixes across positions, the residual carries it forward, the FFN transforms it, and norm keeps the stream stable.
Encoder block (used by BERT, T5 encoder)
x → LN → MHA(self) → + → LN → FFN → + → out
                     ^              ^
                     |              |
                     └── residual ──┘
Encoder is bidirectional. No masking. All positions see all positions.
Decoder block (used by GPT, T5 decoder)
x → LN → MHA(masked self) → + → LN → MHA(cross to encoder) → + → LN → FFN → + → outDecoder has three sublayers per block. The middle one, cross-attention, is the only place information flows from encoder to decoder. In a pure decoder-only architecture (GPT), cross-attention is omitted and you just have masked self-attention + FFN.
Pre-norm vs post-norm
Original paper: x + sublayer(LN(x)) vs LN(x + sublayer(x)). Post-norm lost favor around 2019, it is harder to train deeply without careful warmup. Pre-norm (LN before sublayer) is the 2026 default: Llama, Qwen, GPT-3+, Mistral all use it.
The 2026 modernized block
Vaswani 2017 shipped LayerNorm + ReLU. Modern stacks replaced both. What production blocks actually look like:
| Component | 2017 | 2026 |
|---|---|---|
| Normalization | LayerNorm | RMSNorm |
| FFN activation | ReLU | SwiGLU |
| FFN expansion | 4× | 2.6× (SwiGLU uses three matrices, total params match) |
| Position | Sinusoidal absolute | RoPE |
| Attention | Full MHA | GQA (or MLA) |
| Bias terms | Yes | No |
RMSNorm drops the mean-centering of LayerNorm (one fewer subtraction), which saves compute and is empirically at least as stable. SwiGLU (Swish(W1 x) ⊙ W3 x) consistently outperforms ReLU/GELU FFN by ~0.5 point ppl in the Llama, PaLM and Qwen papers.
Parameter count
For one block with d_model = d and FFN expansion r:
- MHA:
4 · d²(Q, K, V, O projections) - FFN (SwiGLU):
3 · d · (r · d)≈3rd² - Norms: negligible
At d = 4096, r = 2.6, layers = 32 (roughly Llama 3 8B), total: 32 · (4·4096² + 3·2.6·4096²) ≈ 32 · (16 + 32) M = ~1.5B parameters per layer × 32 ≈ 7B (plus embeddings and head). Matches published counts.
Build It
Step 1: the building blocks
Using the tiny Matrix class from Lesson 03 (copied to this file for independence):
layer_norm(x, eps=1e-5)subtract mean, divide by std.rms_norm(x, eps=1e-6)divide by RMS. No mean subtraction.gelu(x)andsilu(x) * W3 x(SwiGLU).ffn_swiglu(x, W1, W2, W3).encoder_block(x, params)anddecoder_block(x, enc_out, params).
See code/main.py for the full wiring.
Step 2: wire a 2-layer encoder and a 2-layer decoder
Stack them. Pass the encoder output into every decoder cross-attention. Add a final LN before the output projection.
def encode(tokens, params):
    x = embed(tokens, params.emb) + sinusoidal(len(tokens), params.d)
    for block in params.encoder_blocks:
        x = encoder_block(x, block)
    return x

def decode(target_tokens, encoder_out, params):
    x = embed(target_tokens, params.emb) + sinusoidal(len(target_tokens), params.d)
    for block in params.decoder_blocks:
        x = decoder_block(x, encoder_out, block)
    return x
Step 3: run forward on a toy example
Feed a 6-token source and a 5-token target through. Verify the output shape is (5, vocab). No training, this lesson is about the architecture, not the loss.
Step 4: swap in RMSNorm + SwiGLU
Replace LayerNorm and ReLU-FFN with RMSNorm and SwiGLU. Confirm shapes still match. This is the 2026 modernization with one function substitution.
Use It
The PyTorch/TF reference implementations: nn.TransformerEncoderLayernn.TransformerDecoderLayer. But most 2026 production code rolls its own block because:
- Flash Attention is called inside attention, not via
nn.MultiheadAttention. - GQA / MLA are not in the stdlib reference.
- RoPE, RMSNorm, SwiGLU are not the PyTorch defaults.
HF transformers has clean reference blocks you should read: modeling_llama.py is the canonical 2026 decoder-only block. It's ~500 lines and worth walking through once.
Encoder vs decoder vs encoder-decoder, when to pick:
| Need | Pick | Example |
|---|---|---|
| Classification, embeddings, QA over text | Encoder-only | BERT, DeBERTa, ModernBERT |
| Text generation, chat, code, reasoning | Decoder-only | GPT, Llama, Claude, Qwen |
| Structured input → structured output (translation, summarization) | Encoder-decoder | T5, BART, Whisper |
Decoder-only won language because it scales cleanest and handles both comprehension and generation. Encoder-decoder is still best when the input has a clear "source sequence" identity (translation, speech recognition, structured tasks).
Ship It
See outputs/skill-transformer-block-reviewer.md. The skill reviews a new transformer block implementation against the 2026 defaults and flags missing pieces (pre-norm, RoPE, RMSNorm, GQA, FFN expansion ratio).
Exercises
- Easy. Count the parameters in your encoder_block at
d_model=512, n_heads=8, ffn_expansion=4, swiglu=True. Validate by implementing the block and usingsum(p.numel() for p in block.parameters()). - Medium. Switch from post-norm to pre-norm. Initialize both and measure the activation norm after 12 stacked layers on random input. Post-norm's activations should explode; pre-norm's should stay bounded.
- Hard. Implement a 4-layer encoder-decoder on a toy copy task (copy
xreversed). Train 100 steps. Report loss. Swap in RMSNorm + SwiGLU + RoPE, does loss drop?
Key Terms
| Term | What people say | What it actually means |
|---|---|---|
| Block | "One transformer layer" | Stack of norm + attention + norm + FFN, wrapped in residual connections. |
| Residual | "Skip connection" | x + f(x) output; enables gradient flow through deep stacks. |
| Pre-norm | "Normalize before, not after" | Modern: x + sublayer(LN(x)). Trains deeper without warmup gymnastics. |
| RMSNorm | "LayerNorm without the mean" | Divide by RMS; one less op, same empirical stability. |
| SwiGLU | "The FFN everyone switched to" | Swish(W1 x) ⊙ W3 x → W2. Beats ReLU/GELU on LM ppl. |
| Cross-attention | "How the decoder sees the encoder" | MHA with Q from decoder, K/V from encoder outputs. |
| FFN expansion | "How wide the middle MLP is" | Ratio of hidden-size to d_model, usually 4 (LayerNorm) or 2.6 (SwiGLU). |
| Bias-free | "Drop the +b terms" | Modern stacks omit biases in linear layers; slight ppl improvement, smaller model. |
Further Reading
- Vaswani et al. (2017). Attention Is All You Needoriginal block spec.
- Xiong et al. (2020). On Layer Normalization in the Transformer Architecturewhy pre-norm beats post-norm deeply.
- Zhang, Sennrich (2019). Root Mean Square Layer NormalizationRMSNorm.
- Shazeer (2020). GLU Variants Improve Transformerthe SwiGLU paper.
- HuggingFace
modeling_llama.pycanonical 2026 decoder-only block.
The full code
Every file for this lesson. Copy it, run it, then change it.
# Full transformer in Julia: encoder + decoder blocks (pre-norm), multi-head
# attention, SwiGLU FFN, LayerNorm and RMSNorm forward + backward gradient
# check against finite differences. Stdlib only. Sources:
#   https://arxiv.org/abs/1706.03762
#   https://arxiv.org/abs/1910.07467
#   https://docs.julialang.org/en/v1/stdlib/LinearAlgebra/

using Random
using LinearAlgebra
using Printf


function randn_matrix(rng::AbstractRNG, rows::Int, cols::Int;
                     scale::Union{Nothing, Float64}=nothing)::Matrix{Float64}
    s = scale === nothing ? sqrt(2.0 / (rows + cols)) : scale
    return s .* randn(rng, rows, cols)
end


function softmax_rows(M::Matrix{Float64};
                     mask::Union{Nothing, Matrix{Bool}}=nothing)::Matrix{Float64}
    out = similar(M)
    rows, cols = size(M)
    for i in 1:rows
        row = M[i, :]
        if mask !== nothing
            row = [mask[i, j] ? -Inf : row[j] for j in 1:cols]
        end
        finite = filter(isfinite, row)
        m = isempty(finite) ? 0.0 : maximum(finite)
        e = [isfinite(v) ? exp(v - m) : 0.0 for v in row]
        s = sum(e)
        out[i, :] = s > 0 ? e ./ s : zeros(cols)
    end
    return out
end


function layer_norm(X::Matrix{Float64}; eps::Float64=1e-5)::Matrix{Float64}
    out = similar(X)
    for i in 1:size(X, 1)
        row = X[i, :]
        mu = sum(row) / length(row)
        var = sum((row .- mu) .^ 2) / length(row)
        denom = sqrt(var + eps)
        out[i, :] = (row .- mu) ./ denom
    end
    return out
end


function rms_norm(X::Matrix{Float64}; eps::Float64=1e-6)::Matrix{Float64}
    out = similar(X)
    for i in 1:size(X, 1)
        row = X[i, :]
        rms = sqrt(sum(row .* row) / length(row) + eps)
        out[i, :] = row ./ rms
    end
    return out
end


function layer_norm_backward(X::Matrix{Float64}, dY::Matrix{Float64};
                            eps::Float64=1e-5)::Matrix{Float64}
    rows, d = size(X)
    dX = similar(X)
    for i in 1:rows
        x = X[i, :]
        dy = dY[i, :]
        mu = sum(x) / d
        xc = x .- mu
        var = sum(xc .* xc) / d
        denom = sqrt(var + eps)
        xhat = xc ./ denom
        dxhat = dy
        dvar = sum(dxhat .* xc) * -0.5 * (var + eps) ^ (-1.5)
        dmu = sum(dxhat .* (-1.0 ./ denom)) + dvar * sum(-2.0 .* xc) / d
        dX[i, :] = dxhat ./ denom .+ dvar .* 2.0 .* xc ./ d .+ dmu / d
    end
    return dX
end


function rms_norm_backward(X::Matrix{Float64}, dY::Matrix{Float64};
                          eps::Float64=1e-6)::Matrix{Float64}
    rows, d = size(X)
    dX = similar(X)
    for i in 1:rows
        x = X[i, :]
        dy = dY[i, :]
        ms = sum(x .* x) / d + eps
        rms = sqrt(ms)
        inv_rms = 1.0 / rms
        dot_dy_x = sum(dy .* x)
        dX[i, :] = dy .* inv_rms .- (x .* (dot_dy_x / (d * ms * rms)))
    end
    return dX
end


function silu(x::Float64)::Float64
    return x / (1.0 + exp(-x))
end


function ffn_swiglu(X::Matrix{Float64}, W1::Matrix{Float64},
                   W2::Matrix{Float64}, W3::Matrix{Float64})::Matrix{Float64}
    h1 = X * W1
    h3 = X * W3
    gated = silu.(h1) .* h3
    return gated * W2
end


function ffn_relu(X::Matrix{Float64}, W1::Matrix{Float64},
                 W2::Matrix{Float64})::Matrix{Float64}
    h = X * W1
    h = max.(h, 0.0)
    return h * W2
end


function scaled_dot_product_attention(Q::Matrix{Float64}, K::Matrix{Float64},
                                     V::Matrix{Float64}; causal::Bool=false)
    dk = size(Q, 2)
    scores = (Q * transpose(K)) ./ sqrt(dk)
    mask = nothing
    if causal
        n = size(scores, 1)
        mask = [j > i for i in 1:n, j in 1:size(scores, 2)]
    end
    weights = softmax_rows(scores; mask=mask)
    return weights * V
end


function multi_head_attention(X::Matrix{Float64},
                             Wq::Matrix{Float64}, Wk::Matrix{Float64},
                             Wv::Matrix{Float64}, Wo::Matrix{Float64};
                             n_heads::Int=1, causal::Bool=false,
                             kv_source::Union{Nothing, Matrix{Float64}}=nothing)
    @assert n_heads > 0 "n_heads must be > 0"
    Q = X * Wq
    kv_input = kv_source === nothing ? X : kv_source
    K = kv_input * Wk
    V = kv_input * Wv
    d_total = size(Q, 2)
    @assert d_total % n_heads == 0 "projected dimension must be divisible by n_heads"
    d_head = d_total ÷ n_heads
    head_outs = Matrix{Float64}[]
    for h in 1:n_heads
        cols = ((h - 1) * d_head + 1):(h * d_head)
        Qh = Q[:, cols]
        Kh = K[:, cols]
        Vh = V[:, cols]
        push!(head_outs, scaled_dot_product_attention(Qh, Kh, Vh; causal=causal))
    end
    concat = hcat(head_outs...)
    return concat * Wo
end


struct BlockParams
    d::Int
    n_heads::Int
    use_swiglu::Bool
    Wq::Matrix{Float64}
    Wk::Matrix{Float64}
    Wv::Matrix{Float64}
    Wo::Matrix{Float64}
    W1::Matrix{Float64}
    W2::Matrix{Float64}
    W3::Matrix{Float64}
    Wq_x::Matrix{Float64}
    Wk_x::Matrix{Float64}
    Wv_x::Matrix{Float64}
    Wo_x::Matrix{Float64}
end


function BlockParams(d::Int, n_heads::Int, ffn_expansion::Float64,
                    rng::AbstractRNG; use_swiglu::Bool=true)
    @assert n_heads > 0 "n_heads must be > 0"
    @assert d % n_heads == 0 "d must be divisible by n_heads"
    h = Int(round(d * ffn_expansion))
    Wq = randn_matrix(rng, d, d)
    Wk = randn_matrix(rng, d, d)
    Wv = randn_matrix(rng, d, d)
    Wo = randn_matrix(rng, d, d)
    W1 = randn_matrix(rng, d, h)
    W2 = randn_matrix(rng, h, d)
    W3 = use_swiglu ? randn_matrix(rng, d, h) : zeros(d, h)
    Wq_x = randn_matrix(rng, d, d)
    Wk_x = randn_matrix(rng, d, d)
    Wv_x = randn_matrix(rng, d, d)
    Wo_x = randn_matrix(rng, d, d)
    return BlockParams(d, n_heads, use_swiglu,
                      Wq, Wk, Wv, Wo, W1, W2, W3,
                      Wq_x, Wk_x, Wv_x, Wo_x)
end


function encoder_block(x::Matrix{Float64}, p::BlockParams)::Matrix{Float64}
    h = rms_norm(x)
    a = multi_head_attention(h, p.Wq, p.Wk, p.Wv, p.Wo; n_heads=p.n_heads)
    x = x .+ a
    h = rms_norm(x)
    f = p.use_swiglu ? ffn_swiglu(h, p.W1, p.W2, p.W3) : ffn_relu(h, p.W1, p.W2)
    return x .+ f
end


function decoder_block(x::Matrix{Float64}, enc_out::Matrix{Float64},
                      p::BlockParams)::Matrix{Float64}
    h = rms_norm(x)
    a = multi_head_attention(h, p.Wq, p.Wk, p.Wv, p.Wo;
                            n_heads=p.n_heads, causal=true)
    x = x .+ a
    h = rms_norm(x)
    a = multi_head_attention(h, p.Wq_x, p.Wk_x, p.Wv_x, p.Wo_x;
                            n_heads=p.n_heads, kv_source=enc_out)
    x = x .+ a
    h = rms_norm(x)
    f = p.use_swiglu ? ffn_swiglu(h, p.W1, p.W2, p.W3) : ffn_relu(h, p.W1, p.W2)
    return x .+ f
end


function numerical_grad(f, X::Matrix{Float64}; h::Float64=1e-5)::Matrix{Float64}
    out = similar(X)
    for i in 1:length(X)
        orig = X[i]
        X[i] = orig + h
        plus = f(X)
        X[i] = orig - h
        minus = f(X)
        X[i] = orig
        out[i] = (plus - minus) / (2h)
    end
    return out
end


function gradient_check_layer_norm()
    println("=" ^ 60)
    println("LAYER NORM: ANALYTIC vs NUMERICAL GRADIENT")
    println("=" ^ 60)
    rng = MersenneTwister(0)
    X = randn(rng, 4, 6)
    rng_v = MersenneTwister(1)
    v = randn(rng_v, 4, 6)

    loss_fn = Y -> sum(layer_norm(Y) .* v)
    analytic = layer_norm_backward(X, v)
    numeric = numerical_grad(loss_fn, copy(X))
    err = maximum(abs.(analytic .- numeric))
    @printf("\nMax abs error (LayerNorm): %.3e\n", err)
end


function gradient_check_rms_norm()
    println("\n" * "=" ^ 60)
    println("RMS NORM: ANALYTIC vs NUMERICAL GRADIENT")
    println("=" ^ 60)
    rng = MersenneTwister(2)
    X = randn(rng, 4, 6)
    rng_v = MersenneTwister(3)
    v = randn(rng_v, 4, 6)

    loss_fn = Y -> sum(rms_norm(Y) .* v)
    analytic = rms_norm_backward(X, v)
    numeric = numerical_grad(loss_fn, copy(X))
    err = maximum(abs.(analytic .- numeric))
    @printf("\nMax abs error (RMSNorm): %.3e\n", err)
end


function compare_norm_outputs()
    println("\n" * "=" ^ 60)
    println("LAYERNORM vs RMSNORM OUTPUTS")
    println("=" ^ 60)
    rng = MersenneTwister(7)
    X = randn(rng, 3, 6)
    Y_ln = layer_norm(X)
    Y_rms = rms_norm(X)
    println("\nLayerNorm row means (should be ~0):")
    for i in 1:3
        @printf("  row %d: mean=%+.6f  std=%.6f\n",
                i, sum(Y_ln[i, :]) / 6, sqrt(sum(Y_ln[i, :] .^ 2) / 6))
    end
    println("\nRMSNorm row RMS (should be ~1):")
    for i in 1:3
        @printf("  row %d: mean=%+.6f  rms=%.6f\n",
                i, sum(Y_rms[i, :]) / 6, sqrt(sum(Y_rms[i, :] .^ 2) / 6))
    end
    println("\nRMSNorm leaves the row mean intact; LayerNorm centers it.")
end


function demo_full_transformer()
    println("\n" * "=" ^ 60)
    println("FULL TRANSFORMER FORWARD PASS")
    println("=" ^ 60)
    rng = MersenneTwister(42)
    d = 8
    n_heads = 2
    ffn_exp = 2.0
    src_len = 6
    tgt_len = 5

    src = randn_matrix(rng, src_len, d; scale=0.5)
    tgt = randn_matrix(rng, tgt_len, d; scale=0.5)

    enc_params = [BlockParams(d, n_heads, ffn_exp, rng) for _ in 1:2]
    dec_params = [BlockParams(d, n_heads, ffn_exp, rng) for _ in 1:2]

    enc_out = src
    for p in enc_params
        enc_out = encoder_block(enc_out, p)
    end

    dec_out = tgt
    for p in dec_params
        dec_out = decoder_block(dec_out, enc_out, p)
    end

    @printf("\nsource shape:           (%d, %d)\n", size(src, 1), size(src, 2))
    @printf("encoder output shape:   (%d, %d)\n", size(enc_out, 1), size(enc_out, 2))
    @printf("target shape:           (%d, %d)\n", size(tgt, 1), size(tgt, 2))
    @printf("decoder output shape:   (%d, %d)\n", size(dec_out, 1), size(dec_out, 2))
    println("\nfirst 3 rows of encoder output:")
    for i in 1:3
        println("  " * join([@sprintf("%+.3f", enc_out[i, j]) for j in 1:4], "  "))
    end
    println("\nfirst 3 rows of decoder output:")
    for i in 1:3
        println("  " * join([@sprintf("%+.3f", dec_out[i, j]) for j in 1:4], "  "))
    end
    println("\nstack: 2-layer encoder + 2-layer decoder, pre-norm, RMSNorm, SwiGLU.")
end


function main()
    compare_norm_outputs()
    gradient_check_layer_norm()
    gradient_check_rms_norm()
    demo_full_transformer()
end


if abspath(PROGRAM_FILE) == @__FILE__
    main()
end